The AI behind Kkgevara
OCR, NLP, and machine learning working together to turn invoices and receipts into clean, categorized, approved financial data — with GPU-accelerated inference on our roadmap as we scale.
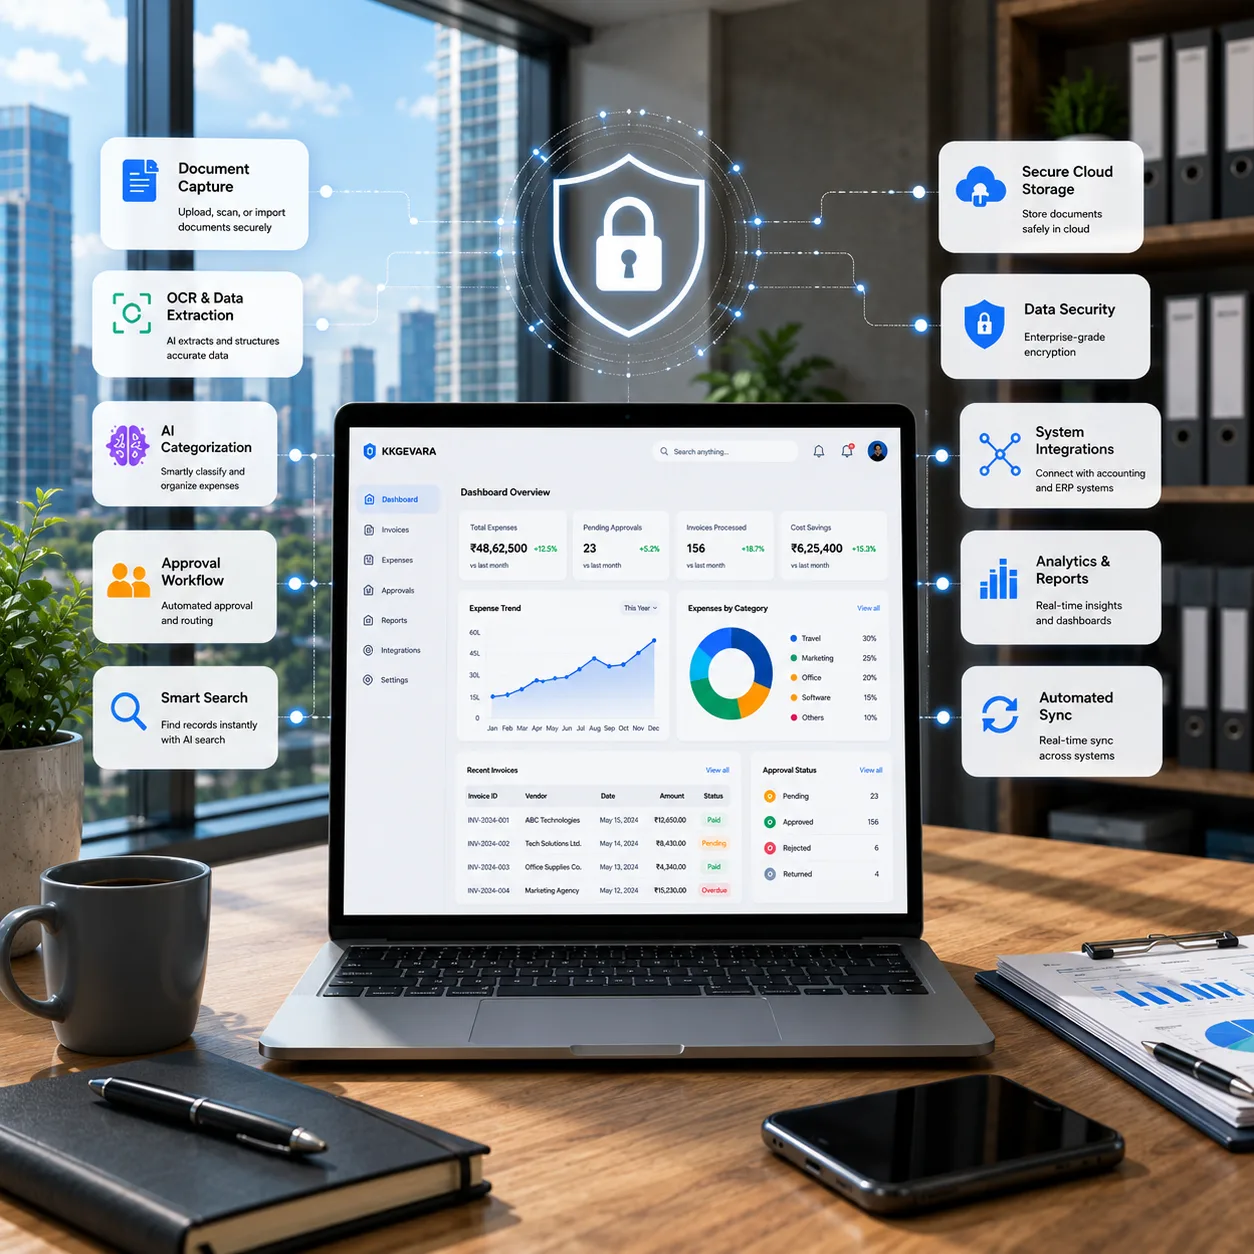
- Upload to extracted data
- < 1 min
- Review before approval
- Human
The pipeline
From document to data in six steps
Every invoice or receipt moves through the same automated pipeline before it reaches your books.
Step 01
Capture
Invoices and receipts come in as PDFs, images, or email attachments.
Step 02
OCR & Document Understanding
Vision models read layout and text to locate vendors, amounts, dates, and line items.
Step 03
NLP Field Extraction
Language models turn raw extracted text into clean, structured fields.
Step 04
ML Categorization
Machine learning assigns each expense to the right accounting category.
Step 05
Fraud & Anomaly Detection
Models flag duplicate invoices and unusual spending patterns before approval.
Step 06
Workflow & Sync
Approved records route through your workflow and sync to your accounting system.
The stack
What’s actually running under the hood
The AI, ML, and infrastructure components that power invoice and expense automation.
OCR & Document Intelligence
Reads printed and scanned invoices, receipts, and financial documents, extracting text and layout together rather than as flat strings.
Natural Language Processing
Converts unstructured invoice and receipt text into structured fields — vendor, tax, totals, and line items.
ML-Based Expense Categorization
Learns from transaction patterns to automatically classify expenses into the right accounting categories.
Fraud & Anomaly Detection
Compares incoming invoices against history to catch duplicates and outlier spending before money moves.
Workflow Automation
Configurable, multi-level approval routing based on amount, department, or custom rules.
Real-Time Analytics
Live dashboards and reports over processed invoices, expenses, and approvals.
REST APIs
A documented API surface for invoice upload, expense management, search, and webhooks.
Cloud Infrastructure
Runs on cloud infrastructure built to scale document volume up or down with demand.
Secure Data Processing
Financial documents and extracted data are encrypted in transit and at rest.
Scaling with NVIDIA GPUs
As document volume grows, we’re planning to move OCR, NLP, and categorization inference onto NVIDIA GPU-accelerated infrastructure — cutting per-document latency and handling far higher throughput than CPU-based inference alone.
What GPU inference is planned to bring
- Faster document turnaround at scale
- Higher throughput per document
- Lower cost per inference
- Room to run larger models
Security
Built with security in mind
Financial documents are sensitive. Every document and extracted field is encrypted in transit and at rest, access is scoped and logged, and infrastructure is designed to isolate customer data.
- Encryption in transit and at rest
- Scoped, logged access to financial data
- Isolated customer environments
Encrypted
In transit and at rest
Access control
Scoped, logged access
Isolated infra
Per-customer separation
Audit trail
Tracked document history
See the technology in action
Talk to our team or explore the platform to see how the pipeline handles your invoices and expenses.